

 As PostgreSQL databases grow, where backup data is written and compressed can affect storage, network bandwidth, and database server resources.
Choosing where backups run: the --target option
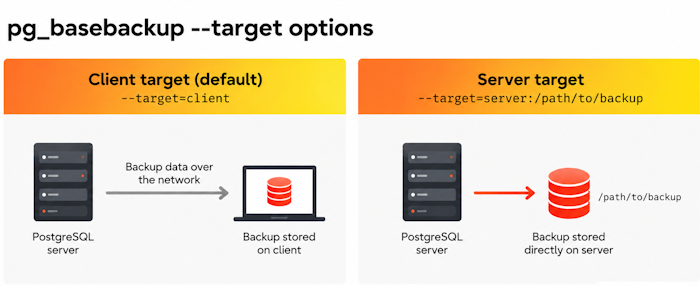
 By default, pg_basebackup sends the backup to the machine where the command is running. For a large PostgreSQL database cluster, that can consume significant network bandwidth and client-side storage. The --target option lets you write the backup directly to the database server instead.
This is useful when bandwidth between the PostgreSQL server and backup client is constrained, because the base backup no longer has to be transferred to the client.
pg_basebackup creates physical backups of the database cluster, including the files in its data directory. For logical backups of individual databases or database objects, PostgreSQL provides tools such as pg_dump.
The syntax:
pg_basebackup [OPTION]...
-t, --target=TARGET[:DETAIL]   backup target (if other than client)
The default target is client, so when --target is omitted, the backup files are created on the machine where pg_basebackup is running. The backup can also include additional tablespaces associated with the cluster. Setting --target=server:/backups/adhoc/ instead stores the backup on the PostgreSQL server at that path.
Two prerequisites need to be in place before --target=server will work.
First, the WAL method (--wal-method or -X) must be set to either none or fetch. The stream method cannot be used with a server backup target because WAL streaming is performed by pg_basebackup on the client. Since stream is the default WAL method, you need to explicitly select fetch or none when using --target. Otherwise, the command fails:
[postgres@fep-client ~]$ pg_basebackup -h 40.126.246.181 -p 65010 -U bkpuser -t server:/database/bkup
pg_basebackup: error: WAL cannot be streamed when a backup target is specified
pg_basebackup: hint: Try "pg_basebackup --help" for more information.
Second, the replication user needs the pg_write_server_files role or superuser privileges:
[postgres@fep-client ~]$ pg_basebackup -h 40.126.246.181 -p 65010 -U bkpuser -t server:/database/bkup -X none
Password:
pg_basebackup: error: could not initiate base backup: ERROR: must be superuser or have privileges of the pg_write_server_files role to create backup stored on server
Grant the role and retry:
postgres=# GRANT pg_write_server_files TO bkpuser;
GRANT ROLE
Example: running a server-side backup
With the WAL method set and the role granted, the backup runs successfully:
[postgres@fep-client ~]$ pg_basebackup -h 40.126.246.181 -p 65010 -U bkpuser -t server:/database/bkup -X fetch -v
Password:
pg_basebackup: initiating base backup, waiting for checkpoint to complete
pg_basebackup: checkpoint completed
pg_basebackup: write-ahead log start point: 0/21000028 on timeline 1
pg_basebackup: write-ahead log end point: 0/21000100
pg_basebackup: base backup completed
The files land on the server itself, not the client:
[postgres@fep15-lab ~]$ ls -l /database/bkup/
total 48912
-rw-------. 1 postgres postgres    183293 Jan 23 12:08 backup_manifest
-rw-------. 1 postgres postgres  49898496 Jan 23 12:08 base.tar
The resulting backup_manifest records information about the files included in the backup and can be used with pg_verifybackup to verify its integrity.
Backup compression option --compress
Compression solves a different problem from --target: where compression happens and which system takes on the CPU overhead.
The syntax:
-Z, --compress=[{client|server}-]METHOD[:DETAIL]   compress on client or server as specified
-Z, --compress=none                               do not compress tar output
The compression method can be gzip, lz4, zstd, or none. You can also provide a plain integer: 0 disables compression, while a value greater than 0 uses gzip at the specified compression level. If you specify a method without a compression level, PostgreSQL uses that method's default level. Optional settings include level, long, and workers, although availability depends on the compression method.
When --compress is set to server, compression happens before the backup is transferred to the client. This reduces network traffic but moves the CPU cost onto the PostgreSQL server, making it useful when bandwidth is constrained and server CPU capacity is available.
[postgres@fep-client ~]$ pg_basebackup -h 40.126.246.181 -p 65010 -U bkpuser -F t -D /u01/fep15 --compress=server-gzip:9 -v
Password:
pg_basebackup: initiating base backup, waiting for checkpoint to complete
pg_basebackup: checkpoint completed
pg_basebackup: write-ahead log start point: 0/2F000028 on timeline 1
pg_basebackup: write-ahead log end point: 0/2F000100
pg_basebackup: base backup completed
[postgres@fep-client ~]$ ls -l /u01/fep15/
total 20748
-rw-------. 1 postgres postgres    183115 Jan 23 04:45 backup_manifest
-rw-------. 1 postgres postgres   4279319 Jan 23 04:45 base.tar.gz
-rw-------. 1 postgres postgres  16778752 Jan 23 04:45 pg_wal.tar
One detail to be aware of is WAL compression. When the default -X stream WAL method is used, server-side compression does not apply to the streamed WAL. To compress the WAL as part of the backup, use client-side compression or -X fetch.
Setting --compress to client instead runs compression on the machine where pg_basebackup was invoked. The backup data crosses the network before it is compressed, so this requires more network bandwidth. In return, the CPU-intensive compression work is moved away from the database server and onto the client.
[postgres@fep-client ~]$ pg_basebackup -h 40.126.246.181 -p 65010 -U bkpuser -F t -D /u01/fep16 -X fetch --compress=client-lz4:7 -v
Password:
pg_basebackup: initiating base backup, waiting for checkpoint to complete
pg_basebackup: checkpoint completed
pg_basebackup: write-ahead log start point: 0/3C000028 on timeline 1
pg_basebackup: write-ahead log end point: 0/3C000138
pg_basebackup: base backup completed
[postgres@fep-client ~]$ ls -l /u01/fep16/
total 5268
-rw-------. 1 postgres postgres    183467 Jan 23 06:17 backup_manifest
-rw-------. 1 postgres postgres   5209066 Jan 23 06:17 base.tar.lz4
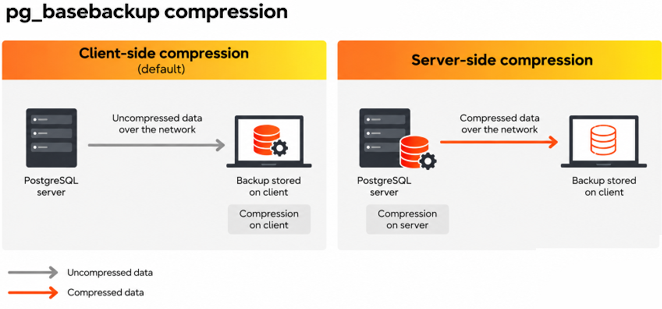
Client-side compression is the default when neither client nor server is specified. The exception is when --target is used. Because the backup is not sent to the client in that case, PostgreSQL uses server-side compression instead.
| Client-side compression | Server-side compression | |
| What's offloaded | Compression CPU work moves to the clien | Compression CPU work runs on the database server |
| Network impact | Backup data crosses the network before compression | Backup data is compressed before transfer, reducing bandwidth use |
| Best suited to | Environments where database server CPU is the tighter constraint and the network can handle the uncompressed backup stream | Bandwidth-constrained environments where the database server has CPU capacity available |
| Interaction with --target | Not available with a server backup target | Used when a server backup target is specified |
Weighing security posture alongside CPU and bandwidth matters too: a compressed backup file is still a full copy of your data, wherever it ends up sitting.
Where pg_basebackup fits in an enterprise backup strategy
 A successful pg_basebackup run proves the tool works. It doesn't prove you have anenterprise backup and recovery strategy.
That distinction matters when recovery becomes an operational issue. IBM’s 2024 Cost of a Data Breach survey found that 70% of breached organizations experienced significant or moderate operational disruption, reinforcing why recoverability matters beyond simply completing a backup job.
pg_basebackup has some important structural limits. Before PostgreSQL 17, every pg_basebackup supported full backups only. PostgreSQL 17 added native incremental backup support using WAL summarization, but pg_basebackup still doesn't provide parallel backup, a centralized backup catalog, retention policy management, or scheduling.
A dedicated backup tool can manage that lifecycle instead of requiring DBAs to script it themselves. pgBackRest provides full, differential, and incremental backups, parallel processing, retention management, and scheduling for PostgreSQL physical backups.
Fujitsu Enterprise Postgres packages pgBackRest as a supported backup utility, a capability introduced with Fujitsu Enterprise Postgres 15 SP1. DBAs can therefore combine controls such as --target and --compress with an incremental, catalog-managed workflow. pgBackRest also supports scenarios such as re-synchronizing a former primary as a standby without requiring another full backup. See Fujitsu's high-speed backup and recovery overview for the broader capability set.
Backup tooling is only one part of that operating model. Enterprise PostgreSQL support for mission-critical operations also needs to account for how backup and recovery processes are supported when something goes wrong.
A completed pg_basebackup run, even a well-compressed one landing in exactly the right place, is not the same thing as an enterprise backup and recovery operating model. That model still needs:
- Tested restores
Run restore tests on a defined schedule so recoverability is verified rather than inferred from a successful backup job. That includes testing failure cases such as restoring into a destination where the target objects already exist. - A documented retention policy
Define which backups and WAL files are retained, for how long, and when they are removed. - Off-site copies
Keep backup copies outside the primary failure domain so a storage or site failure cannot remove both the production database and its backups. - Monitoring and alerting
Monitor backup jobs and surface failures automatically rather than relying on manual checks.
pg_basebackup vs. pgBackRest vs. Barman: a quick comparison
| Tool | Incremental backup | Parallelism | Backup catalog and retention |
| pg_basebackup | Native since PostgreSQL 17 using WAL summarization | No parallel backup | No built-in catalog or retention management |
| pgBackRest | Yes, including differential and incremental backups | Yes, including parallel backup and restore | Yes, with configurable retention |
| Barman | Yes. Supports file-level incremental backups and PostgreSQL 17 block-level incremental backups | Depends on the backup method; streaming backups using pg_basebackup do not provide parallel backup | Yes, with centralized backup management and retention policies |
The right tool depends on the wider backup architecture. pg_basebackup provides PostgreSQL's native physical backup capability, while pgBackRest and Barman add management capabilities for operating backup and recovery across larger or more complex environments.
Before we go
--target and --compress solve a real operational problem: deciding where a backup lands and where its compression cost is paid, especially when network bandwidth or client-side storage becomes the constraint. They don't turn pg_basebackup into a complete enterprise backup strategy on their own.
See how Fujitsu Enterprise Postgres pairs pg_basebackup's --target and --compress options with a packaged pgBackRest workflow in a trial environment.
Frequently asked questions about pg_basebackup
Can pg_basebackup take incremental backups?
Yes. PostgreSQL 17 introduced native incremental backups using WAL summarization. The --incremental option references the backup manifest from an earlier backup, allowing pg_basebackup to capture changed blocks instead of another full copy. pg_combinebackup then combines the dependent backups into a synthetic full backup for recovery.
Is pg_basebackup enough for enterprise disaster recovery on its own?
No. pg_basebackup creates physical backups that can support disaster recovery, but it doesn't provide the complete operating model around them. A base backup can be used for point-in-time recovery (PITR) when combined with the required WAL segments, and it can provide the starting point for a log-shipping or streaming replication standby server. For environments that also use logical replication, failover slot synchronization can keep logical replication slots available on standby servers so subscribers can reconnect after failover without a full resynchronization. Enterprise recovery still needs tested restores, WAL archiving, retention management, off-site copies, scheduling, and monitoring.
What's the difference between the default backup target and --target=server?
The default target writes the backup to the machine running pg_basebackup, while --target=server writes it to the PostgreSQL server's filesystem. With the default client target, pg_basebackup can create the backup in plain or tar format, depending on the selected format. A server target is always written in tar format and requires appropriate server-side permissions. It also cannot be used with the default stream WAL method, so WAL must use fetch or none.
Which compression methods does pg_basebackup support?
pg_basebackup supports gzip, LZ4, and Zstandard (zstd) compression. Compression can run on either the client or PostgreSQL server, letting you choose whether to prioritize database-server CPU or network bandwidth. Server-side compression reduces the amount of backup data transferred across the network, while client-side compression moves that CPU work away from the database server. Client-side compression requires tar-format output. With plain-format backups, server-side compression can still reduce the data transferred over the network because the client decompresses the backup as it receives it.

Fujitsu Enterprise Postgres
provides to harness your data.
 PostgreSQL Insider
has a series of technical articles for PostgreSQL enthusiasts of all stripes, with tips and how-to's.


