

 Your PostgreSQL server won't start, pg_wal is full, and the disk holding the transaction log directory has run out of space.
pg_wal holds PostgreSQL's Write-Ahead Log (WAL), a record of every change written to the database before it's applied to the actual data files. WAL is what lets PostgreSQL guarantee durability and crash recovery. Because PostgreSQL must be able to write to WAL before it can safely make changes to the database, a full pg_wal directory can force it to shut down rather than risk data corruption.
The steps below will help you identify what's filling pg_wal, recover the database safely, and prevent the same problem from happening again.
Why the pg_wal directory fills up
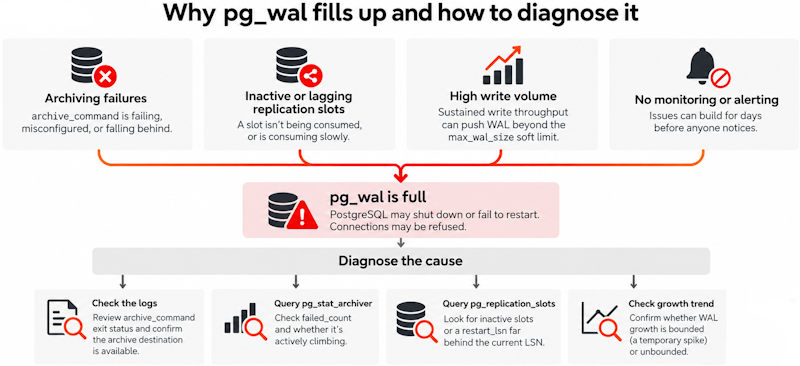
pg_wal typically grows for one of four reasons, and diagnosing which one you're dealing with is most of the work of fixing it.
- Archiving failures
The archive_command is failing, misconfigured, or falling behind, so PostgreSQL can't recycle WAL segments until they're safely archived. - Inactive or lagging replication slots
A replication slot that isn't being consumed, or is consuming slowly, tells PostgreSQL to hold onto WAL indefinitely on its behalf. - High write volume
Sustained write throughput can push WAL beyond max_wal_size, particularly under heavy load or when checkpoints cannot keep pace. max_wal_size is a soft limit, so WAL can grow beyond it. - No monitoring or alerting
Any of the above can build for days before anyone notices, simply because nothing is watching disk utilization or archiver health.
Two PostgreSQL views can help you identify the cause quickly: pg_stat_archiver.failed_count shows whether archiving is failing, while pg_replication_slots and its restart_lsn value show whether a replication slot is retaining WAL.
How inactive or lagging replication slots cause WAL buildup
A replication slot exists to guarantee that WAL isn't removed until whatever is consuming it, such as a standby, a logical replication subscriber, or a CDC tool, has caught up. If that consumer stops or falls too far behind, PostgreSQL continues retaining the WAL it needs by default. A standby that was decommissioned without dropping its slot, or a logical subscriber that remains offline, can quietly fill a disk this way even when WAL archiving is working correctly.
What happens when pg_wal fills up
When pg_wal runs out of disk space, PostgreSQL may shut down because it can no longer safely write the WAL files needed to record database changes. You'll typically see messages like these in the PostgreSQL log:
WARNING: terminating connection because of crash of another server process
DETAIL: The postmaster has commanded this server process to roll back the current transaction and exit because another server process exited abnormally and possibly corrupted shared memory.
HINT: In a moment you should be able to reconnect to the database and repeat your command. server closed the connection unexpectedly
This probably means the server terminated abnormally before or while processing the request. The connection to the server was lost. Attempting reset: Failed.
Trying to connect a new session afterward produces this:
-bash-4.2$ psql -p 5438 postgres
psql: could not connect to server: No such file or directory
Is the server running locally and accepting connections on Unix domain socket "/var/run/postgresql/.s.PGSQL.5438"?
The symptoms are the same whether pg_wal filled because of an archiving failure, a replication slot, sustained write volume, or a lack of monitoring. They tell you what has happened, but not which underlying issue caused it, so the next step is to diagnose the cause before attempting recovery.
Diagnosing the cause before you change anything
Work through this in order before deciding on a recovery option:
- Check the archive_command exit status in the PostgreSQL logs and confirm the archive destination is available and has the required permissions
- Query pg_stat_archiver for failed_count and whether it's actively climbing
- Query pg_replication_slots for any slot that's inactive or has a restart_lsn far behind the current LSN
- Confirm whether growth is bounded (a temporary spike that's already leveling off) or unbounded (an ongoing failure that will keep consuming disk)
If WAL archiving is enabled, PostgreSQL must retain WAL segments until they have been successfully archived. If the archive_command fails repeatedly or archiving can't keep pace with new WAL, those segments can continue accumulating in pg_wal.
If archiving is the culprit, the PostgreSQL logs may look something like this, with the archive command failing repeatedly until the disk runs out entirely:
sh: /archive/ist5/arc/0000000400000028000000CD: No such file or directory
LOG: archive command failed with exit code 1 (11263)
DETAIL: The failed archive command was: gzip < pg_wal/0000000400000028000000CD >/archive/ist5/arc/0000000400000028000000CD (14792)
PANIC: could not write to file "pg_wal/waltemp.4111": No space left on device
LOG: server process (PID 4111) was terminated by signal 6: Aborted (11206)
LOG: terminating any other active server processes (11203)
LOG: archiver process (PID 4103) exited with exit code 1 (11204)
LOG: connection received: host=[local] (11213)
FATAL: the database system is in recovery mode (11191)
LOG: all server processes terminated; reinitializing (11210)
LOG: database system was interrupted; last known up at 2017-10-04 01:15:41 GMT
LOG: database system was not properly shut down; automatic recovery in progress
LOG: redo starts at 29/8D242168 (10126)
LOG: redo done at 29/9BFFFF88 (10127)
LOG: checkpoint starting: end-of-recovery immediate
PANIC: could not write to file "pg_wal/waltemp.4920": No space left on device
LOG: startup process (PID 4920) was terminated by signal 6: Aborted (11206)
LOG: aborting startup due to startup process failure (11201)
One thing before you go further: never delete WAL files manually from pg_wal.
Removing WAL segments that PostgreSQL still requires can prevent the database from recovering successfully. The recovery options below are designed to restore disk space without simply deleting WAL files from the pg_wal directory.
Recovering when the database won't start
Once you know what's causing the growth, choose the lowest-risk recovery option available. After using any of these options, take a full backup before resuming normal operations.
| Recovery option | What it does | When to use it | Risk level |
| 1 Add space to the partition | Adds disk space to the partition containing pg_wal | Adds disk space to the partition containing pg_wal | Low |
| 2 Move the pg_wal directory to a larger volume | Moves pg_wal to a partition with more available space | Another partition has enough space available | Low to moderate |
| 3 Free space using a reserved placeholder file | Deletes a pre-created dummy file to release reserved disk space | A placeholder file was created before the incident | Moderate |
| 4 Identify and reclaim WAL with pg_archivecleanup | Removes WAL archive files older than the WAL file identified with pg_controldata | The other recovery options aren't available | High |
1 Add space to the partition
Check the available disk space:
df
If possible, add more space to the partition where pg_wal is located, then start the database.
2 Move the pg_wal directory to a larger volume
If another partition has enough space, copy the WAL files to it:
cp -rf /database/inst5/pg_wal/*
/home/transaction/inst5/transactionlog/
Keep a backup of the existing pg_wal directory:
mv pg_wal /home/postgre/pg_wal_bkp
Then create a symbolic link to the new location and start the database:
ln -s /home/transaction/inst5/transactionlog/ pg_wal
Once the database is running and you've confirmed that new WAL files are being written to the new location, remove the backup:
rm -fR /home/postgre/pg_wal_bkp
3 Free space using a reserved placeholder file
If you created a dummy file in advance to reserve emergency disk space, remove it:
rm ONLY_DELETE_THIS_DUMMY_FILE_IN_A_POSTGRES_EMERGENCY
Start the database, connect to PostgreSQL, and run a checkpoint:
psql -d postgres -c "CHECKPOINT;"
Once the database is stable, recreate the dummy file so the reserved space is available for a future emergency.
4 Identify and reclaim WAL with pg_archivecleanupIf you can't use any of the options above, use pg_controldata to identify the WAL file associated with the latest checkpoint:
pg_controldata -D /database/inst5
Database system identifier: 6465070279055498266
Database cluster state: in production
pg_control last modified: Wed 13 Sep 2017 12:07:38 AEST
Latest checkpoint location: 0/F826ACC8
Prior checkpoint location: 0/F8266088
Latest checkpoint's REDO location: 0/F826ACC8
Latest checkpoint's REDO WAL file: 000000010000000F00000026
Use that WAL file with pg_archivecleanup, first with -n to show which files would be removed:
pg_archivecleanup -n /home/transaction/inst5/transactionlog 000000010000000F00000026
If the dry run shows the expected files, rerun the command without -n to remove them:
pg_archivecleanup /home/transaction/inst5/transactionlog 000000010000000F00000026
Start the database and confirm that space has been reclaimed. Then take a full backup before returning to normal operations.
Preventing pg_wal from filling up again
Once you've recovered the database, address the conditions that allowed pg_wal to fill in the first place.
- Tune max_wal_size and min_wal_size for your workload, so PostgreSQL has enough WAL capacity for normal write volume and checkpoint activity.
- Set max_slot_wal_keep_size so an inactive or lagging replication slot can only hold onto a bounded amount of WAL instead of an unlimited amount. If a slot's restart_lsn falls behind the current LSN by more than this setting allows, required WAL may be removed and the standby may no longer be able to continue replication.
- Monitor pg_stat_archiver and pg_replication_slots on a schedule, not only after an incident. Regular checks can identify a failing archiver or lagging replication slot before WAL consumes the available disk space.
- Alert on disk utilization thresholds, such as 70% and 90%, rather than discovering the problem at 100%. This gives your team time to investigate growing WAL before the database runs out of space.
- Keep regular backups and compress archived WAL if storage is a concern. A simple approach:
archive_command = 'gzip < %p > /mnt/server/archivedir/%f.gz'
Recovery then needs the matching decompression step:
restore_command = 'gunzip < /mnt/server/archivedir/%f.gz > %p'
Building monitoring your team can rely on before the next incident
 A full pg_wal directory is often a sign that monitoring didn't surface the problem early enough. You can build pg_stat_archiver and pg_replication_slots into your existing monitoring and alerting so your team can spot archiving failures, replication lag, and growing WAL before disk space becomes critical.
Monitoring can give you earlier warning. The right support model can also give your team somewhere to escalate when an incident needs additional expertise.
Fujitsu Enterprise Postgres provides:
- Support for Fujitsu Enterprise Postgres and community PostgreSQL environments, so teams can get help across mixed PostgreSQL estates.
- 24/7 global support, providing an escalation path when an incident can't wait for the next working day.
- Experienced PostgreSQL support, giving internal teams additional expertise when diagnosing and recovering from database incidents.
The diagnosis and recovery steps don't change depending on whether you're running Fujitsu Enterprise Postgres or community PostgreSQL. The difference is having additional support available when your own team needs it.
See how Fujitsu Enterprise Postgres combines enterprise PostgreSQL with 24/7 support, or start a trial today.
Frequently asked questions about pg_wal
What does it mean when pg_wal is full?
When pg_wal is full, the disk holding PostgreSQL's Write-Ahead Log directory has run out of space. PostgreSQL may shut down or refuse to start rather than risk writing changes it can't safely record. Common causes include failed archiving, an inactive or lagging replication slot, or WAL growth exceeding the available disk space.
Is it safe to manually delete files from the pg_wal directory?
It is not safe to manually delete files from the pg_wal directory. Removing WAL segments PostgreSQL still needs for crash recovery can prevent the database from recovering successfully. Use the appropriate recovery process to identify and reclaim WAL rather than deleting files directly.
What is the difference between pg_wal and pg_xlog?
The difference between pg_wal and pg_xlog is the directory name: pg_wal is the name used by PostgreSQL 10 and later for the directory previously called pg_xlog. The directory was renamed to make its purpose clearer.
How do I stop pg_wal from growing during replication?
To stop pg_wal from growing unchecked during replication, limit how much WAL replication slots can retain and monitor slots for replication lag. Set max_slot_wal_keep_size to cap WAL retention, and monitor pg_replication_slots for inactive or lagging replication slots that could otherwise continue retaining WAL.

Fujitsu Enterprise Postgres
provides to harness your data.
 PostgreSQL Insider
has a series of technical articles for PostgreSQL enthusiasts of all stripes, with tips and how-to's.


